Monday, November 6, 2023

Etnaviv NPU update 10: Upstreaming and TP jobs update

 If you remember the last update two weeks ago, I got MobileNetV1 working with good performance, and I was planning to move to upstreaming my changes to the Linux kernel and Mesa.

One of the kernel patches is now queued for the 6.7 release of the Linux kernel, and the other one has just been resent for reviews.

Regarding Mesa, I have made several cleanups and have started getting great review comments from Christian Gmeiner.

While waiting for feedback, I have started work on using the TP cores for tensor manipulation, which should be many times faster  than the naive code I was running on the CPU for this.

Got some jobs producing the correct results, but I'm facing a problem with the GPU hanging right afterwards. Have already made a pass at the whole set of data that is sent to the HW (unit configuration, command stream and registers), but haven't found yet the problem. I will next improve the tooling around this and get a better view of the differences.

I hacked Mesa to use the out-of-tree driver and my code works that way, so it has to be something at the kernel driver.

During the next weeks I will keep incorporating feedback and see how I can fix the GPU hang on TP jobs.


Monday, October 23, 2023

Etnaviv NPU update 9: We got there!

Progress

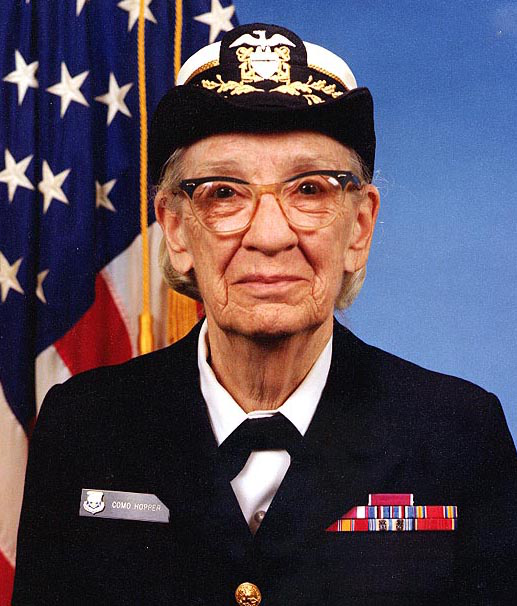
Since the last update I finally got the whole of MobileNetv1 running at full-accuracy on the NPU with Mesa: 
tomeu@arm-64:~/mesa$ python3.10 classification.py -i grace_hopper.bmp -m mobilenet_v1_1.0_224_quant.tflite -l labels_mobilenet_quant_v1_224.txt -e libteflon.so
Loading external delegate from libteflon.so with args: {}
Processing the input took 18 ms.
Running the NN job took 13 ms.
Processing the output took 1 ms.
0.866667: military uniform
0.031373: Windsor tie
0.015686: mortarboard
0.007843: bow tie
0.007843: academic gown
time: 33.094ms
That takes us to a performance level around 3 times faster than running the same inference on the CPUs on the A311D SoC.

Most of the time (18 ms.) is spent in my naive manipulation of the input tensor, transposing and reshuffling it to match what the HW expects. Once we learn to do these operations on the 4 tensor manipulation cores, this time should be brought close to zero.

The 13 ms. that the convolutions take in the NPU is still sensibly higher than the 8 ms. that the blob achieves, but the optimizations mentioned in previous updates in this blog should bring us pretty close.
 

Next steps

Now that we have something that people can use in their products, I will switch to upstreaming mode.

I want to do a few cleanups to the Mesa code and then I will ask for people to review and ack so it can be merged. In the meantime, the draft merge request can be found here.

I would also like to have a CI job running to make sure it doesn't regress. But given that we don't use NIR as of yet and the dependencies with the rest of Mesa are minimal, there is probably little need as long as I'm the only person contributing to the code.


Friday, October 6, 2023

Etnaviv NPU update 8: Finally some inference

Progress

Last week I was a bit distracted with the trip to Paris for the Embedded Recipes conference, but later I have found some time for hacking and got some interesting results out of it.

Refactored the Gallium front-end

As commented in the previous update, I had found some limits in my testing due to the naive way that the front-end was scheduling jobs to the Gallium hardware-dependent driver.

I got to basically rewrite it (and removed any C++ remnants, on the way) and moved to a model in which the drivers would compile the operation blocks that they support to a format that can be quickly sent to the hardware.

As a side effect, I got proper memory management of the workload which allowed me to expand the testing I can do in a reasonable amount of time.

Also took the chance to rewrite the higher level scheduling data structure so all jobs in the same model partition are sent to the hardware in a single batch, for decreased latency.

Unfortunately I didn't get to remove copies of input and output tensors because the TensorFlow Lite API for this (TfLiteAsyncKernel) is undocumented and far from trivial. They seem to just be adding stuff on top to abstract whatever the Android folks may end up wanting to do.

Got MobileNet V1 to run

As part of the refactoring  from above, I got multiple operations in the same model to work, which got us to correctly running some inferences, even if at low accuracy rates:

by Julien Langlois CC BY-SA 3.0

tomeu@arm-64:~/mesa$ LD_PRELOAD=libtensorflow_lite.so python3.10 class_device.py -i hen.bmp -m mobilenet_v1_0.25_224_quant.tflite -l labels_mobilenet_quant_v1_224.txt -e libteflon.so
Loading external delegate from build/src/gallium/targets/teflon/libteflon.so with args: {}
tflite_plugin_create_delegate
Teflon delegate: loaded etnaviv driver
INFO: Initialized TensorFlow Lite runtime.
PrepareDelegate
VERBOSE: Replacing 27 out of 31 node(s) with delegate (Teflon Delegate) node, yielding 2 partitions for the whole graph.
0.960784: hen
0.015686: cock
0.007843: goose
0.003922: Pembroke
0.003922: Ibizan hound
time: 22.802ms
tflite_plugin_destroy_delegate

This matched bit by bit the output from the blob, even if I was doing some tensor operations by hand, on the CPU. That also causes it to run far too slowly. We should be able to get that down to around 5ms once we learn how to drive the TP units for tensor manipulation.

Presented this work at Embedded Recipes 2023

Tired of only writing about all this in this blog, I took the chance given to me by Kevin Hilman to present it in front of a captive audience.


You can find the slides here, and listen to the talk at:


Next steps

The previous update got more in deep into what is left to do in the medium term, so I will just mention what I plan to do in the immediate future:

  1. Get input and output channels working at the 512 level, so we can run a higher accuracy version of the MobileNet V1 network
  2. Learn to use the TP units to remove those costly transpositions and reshuffles in the CPU (at this point, we would have something useful to people on the field)
  3. Upstream changes to the Linux kernel
  4. Propose Teflon to the Mesa folks

Tuesday, September 26, 2023

Etnaviv NPU update 7: Summer is over

Progress

With the kids back in school I have been able to work on the Vivante VIP NPU driver full-time during the two weeks after the last update, with quite some work coming out of the pipeline:

Found the problem with enabling the 8th NN core

Though I don't know exactly yet what the problem is, I found that by going back to a previous brute-force approach to powering up the NPU, the 8th core works just fine.

For now this unblocks the work and gets me closer to the initial goal of running a MobileNetv1 inference and seeing what the performance is like, so I'm leaving a proper fix for this for later.

I bet there's either a register that is being written in the wrong order, or a delay between register writes that is too short. Will have to delve into the power domain subsystem and/or the common clock framework in the Linux kernel to fix this one.

Added support for depthwise convolutions

MobileNetV1 introduced Separable Depthwise Convolutions (see the linked paper for an in-depth description), which are layers that contain a depthwise convolution to process each depth level separately, plus a pointwise convolution to rejoin them again. This offers the same result with 23x less multiplications, so it's very attractive for mobile use-cases.

This hardware doesn't support depthwise convolutions directly, but we can lower them to regular convolutions after modifying the weight tensor to cover each IFM/depth separately.

Added support for pointwise convolutions

For the second half of a Separable Depthwise Convolution, I just had to take into account that 1x1 kernels are packed in a different format in memory, as otherwise it would be very inefficient for each NN core to pull each 1-byte kernel separately from the memory bus.

Added support for unsigned weights

TensorFlow Lite has moved towards implementing a new quantization specification which gives preference to signed weights because of convenience, as symmetric quantization is simpler to implement. Unfortunately for us, our hardware works natively with unsigned weights so we would need to convert them if we were to use TFLite's new quantization.

But the models that Google themselves publish make use of the ancient tooling that still support the old, unsigned quantization scheme, so I had to find a way of producing models with unsigned quantization for our test suite, to match what MobileNetV1 does.

That also implied moving to per-tensor quantization, instead of per-axis.

Added support for higher IFMs and OFMs (up to 256 each)

In the previous update I explained how support for multiple input and output channels (or feature maps) was added, but I wasn't able to test with more than 7 output channels because the 8th NN core was MIA.

With that solved, I was able to see what would be needed for convolutions with higher channel counts, such as those that MobileNetV1 use (32, 64, 128, 256, 512 and 1024).

Each level implied revisiting the tiled format in which weights and biases are laid out in memory, making it more and more complex.

I got to 256, with 512 and 1024 bringing more changes in the tiled format that I still need to reverse engineer.


Next steps

Model partition compilation and resource management

I'm facing problems with testing coverage as we support so many different parameters that need to be tested in combination, with a explosion in the number of individual tests. Because of the hacky current state of the TFLite delegate (and Gallium state tracker) I'm not able to run all the tests because I don't have proper resource management implemented and so we reach OOM before the end.

So my next task after I get back from Embedded Recipes will be to refactor the delegate implementation so we have a proper compilation of the model partitions. These will own the weight+bias buffers as well as the intermediate tensors, with each inference just feeding an input tensor to the partition and retrieving an output tensor at the end.

This will allow me to scale up the automated testing further, so I can keep adding new features with confidence, knowing that I'm not adding regressions.

Move development to Cottonwood A311D board

Da Xue of LibreComputer has got Etnaviv and Teflon working on the new boards that his company is releasing soon. One of them contain a A311D SoC, the same as the VIM3 I'm currently using for development. I will be initially targeting that one, and later make sure that it also works on the Cottonwood boards that will have the S905D3 SoC, which has a VIP Pico instead of a VIP Nano.

Besides being in general a great FOSS champion and specifically being supportive of ML inference with open source, Da is directly sponsoring this work, so I look forward to meet him in Paris this week and exchange notes.

Bigger coefficient tensors

The last known features missing before being able to run MobileNetV1 are IFMs and OFMs of 512 and 1024, each.

Hopefully it will only require some further tweaking of the tiled memory representation of the coefficient buffer.

Medium term goals

I don't expect performance to be that great yet, so I plan on switching the focus to it after the above has been accomplished. I expect for the features below making the most impact in improving performance:
  1. Avoid copies in and out of the model partition, by mapping user buffers to the NPU
  2. Use the TP units for tensor manipulation (transposing, mostly)
  3. Properly configuring the automatic caching of kernels and images in the internal on-chip SRAM
  4. Use the external SRAM for intermediate tensor data
  5. Chain all TP and NN jobs in a model partition in the same command stream
  6. Enable zero-run-length compression in the coefficient buffer
  7. Tune the tiling parameters for reduced memory bandwidth usage

Thursday, September 7, 2023

Etnaviv NPU update 6: Almost there!

Progress

 This week started quite fruitfully, these features were added:

  • Convolutions with multiple input and output channels (input and output feature maps)
  • "Same" padding in convolutions

And with this we should have all the features we need to run a model such as MobileNet v1 and get some performance numbers to guide the next steps.

One more roadblock

Only that the NPU hangs when I try to use the 8th core... and this is required to run most detection models, as they start by convoluting the input to 32 feature maps.

Have checked and we are sending to the kernel bit-identical command streams and input buffers, so I suspect the problem will be somewhere in the kernel.

So I plan to instrument the out-of-tree kernel driver and get some register and command stream dumps, in the hope that there is some bit in a magic register somewhere that I need to flip.

Want to try it out?

I'm not really looking forward to such work, so I decided to first invest some time cleaning things up a bit to make it easier for other people to play with this if they wish.

I have removed from my branch everything from my previous attempt at using OpenCL and have written some documentation about how to run the TensorFlow Lite delegate:

https://gitlab.freedesktop.org/tomeu/mesa/-/blob/teflon/docs/teflon.rst

You will need a VIM3 board, a recent mainline kernel and a Debian testing rootfs.


Thursday, August 24, 2023

Etnaviv NPU update 5: Harder convolutions!

Progress

Managed to squeeze some time between holidaying to hack on the NPU driver and got something out of it.

Since the last update I have:

  • implemented support for strided convolutions with more than one input channel, and
  • Implemented support for more than one output channel, but for now only for a single input channel.

Next steps are  to support convolutions with multiple input and output channels, and padding. Then see what is still missing so we can run MobileNet v1 and check the performance when using the NN units and doing the rest on the CPU.

As a reminder, I'm pushing all the code to this branch: https://gitlab.freedesktop.org/tomeu/mesa/-/commits/teflon/.

IRC channel

A bunch of us have started to gather in the #ml-mainline IRC channel in OFTC to disucss matters about doing accelerated ML with mainline, on embedded.

For those of you that may not have a IRC bouncer setup yet, you can easily join with the web chat UI, but in case others aren't in front of the keyboard when you type your question, I recommend using element.io with the Matrix IRC bridge:

https://blog.christophersmart.com/2022/03/21/joining-a-bridged-irc-network-on-element-matrix/

Embedded recipes

I have been invited to give a talk about all this ML with mainline effort at Embedded Recipes 2023, Paris 28-29 September. Slides and a recording will be published after the conference ends.

Sponsor

Last but not least, if I am able to invest so much effort on this is because the folks at LibreComputer have been supporting me financially this last couple of months.

Thanks to Da Xue for his support, it is greatly appreciated! It is awesome to see SBC vendors investing in the Linux upstream ecosystem.

Monday, August 7, 2023

Etnaviv NPU update 4: It's convoluting!

Summer has kept me busy with holidays, but I have managed to find a bit of time to keep hacking on the driver for the VeriSilicon NPU since the last update.

TL;DR

The issue with placing the output to the right scale is solved now, and simple convolution operations are working just fine.

3D tensors are now supported as inputs, and we support strided convolutions as well, but only on 2D inputs for now.

The test workloads are running fast and stably now, so I now feel I have pretty solid ground beneath my feet.

There are three features left before I can run a real, full-fledged commercially interesting model:

  1. 3D inputs for strided convolutions
  2. Multiple output channels
  3. Padded convolutions

Re-quantization

The last update in this blog was left at my attempt at figuring out how the convolution raw outputs had to be processed with fields called post_shift and post_multiplier so I could get the right values in the final output.

After spending more time than I should probably have in a spreadsheet trying to find correlations, some desperate googling brought me to some research papers about optimizing quantization operations on integer-only hardware:

That explains the meaning of the shift and multiplier, as these are the operations we can use to approximate the floating point division on integer hardware.

But to actually understand what the hardware was trying to do with them, it was useful to look at the QNNPACK implementation of requantization.

3D input tensor

This was pretty much straightforward, as was basically a matter of updating the code to take into account the added dimension, and also reorder the tensor elements as the hardware expects depth first order.

This was made much easier by some improvements to the scripts I use to observe the behavior of the closed source stack, by intercepting the communication with the kernel's GPL driver.

For example, this is the output when Mesa has generated a cmd stream that is functionally equivalent to what the blob sends to the kernel:

+ diff -u -U 100 /home/tomeu/mesa.txt /home/tomeu/galcore.txt
--- /home/tomeu/mesa.txt    2023-08-07 18:28:29.939750225 +0200
+++ /home/tomeu/galcore.txt    2023-08-07 18:28:42.116625362 +0200
@@ -1,176 +1,273 @@
 {
-    0x0801028a, /* LOAD_STATE (1) Base: 0x00A28 Size: 1 Fixp: 0 */
-    0x00000011, /*   PA.SYSTEM_MODE := PROVOKING_VERTEX_LAST=1,HALF_PIXEL_CENTER=1 */
-    0x08010e13, /* LOAD_STATE (1) Base: 0x0384C Size: 1 Fixp: 0 */
-    0x00000002, /*   GL.API_MODE := OPENCL */
+    0x00000000, /* UNKNOWN (0) */
+    0x00000000, /*  */
+    0x00000000, /* UNKNOWN (0) */
+    0x00000000, /*  */
+    0x00000000, /* UNKNOWN (0) */
+    0x00000000, /*  */
     0x00000000, /* UNKNOWN (0) */
     0x00000000, /*  */
     0x08010e4f, /* LOAD_STATE (1) Base: 0x0393C Size: 1 Fixp: 0 */
     0x00000000, /*   GL.OCB_REMAP_START := 0x0 */
     0x08010e50, /* LOAD_STATE (1) Base: 0x03940 Size: 1 Fixp: 0 */
     0x00000000, /*   GL.OCB_REMAP_END := 0x0 */
     0x08010e4c, /* LOAD_STATE (1) Base: 0x03930 Size: 1 Fixp: 0 */
     0x00000010, /*   GL.NN_CONFIG := UNK0=0x0,DISABLE_ZDPN=0,DISABLE_SWTILING=0,SMALL_BATCH=1,DDR_BURST_SIZE=0x0,UNK7=0,NN_CORE_COUNT=0x0,UNK12=0 */
     0x08010428, /* LOAD_STATE (1) Base: 0x010A0 Size: 1 Fixp: 0 */
-    0xffff3000, /*   PS.NN_INST_ADDR := *0xffff3000 */
+    0x3348e780, /*   PS.NN_INST_ADDR := *0x3348e780 */
     0x08010429, /* LOAD_STATE (1) Base: 0x010A4 Size: 1 Fixp: 0 */
     0x00000000, /*   0x010A4 */
     0x08010e03, /* LOAD_STATE (1) Base: 0x0380C Size: 1 Fixp: 0 */
     0x00000c23, /*   GL.FLUSH_CACHE := DEPTH=1,COLOR=1,TEXTURE=0,PE2D=0,TEXTUREVS=0,SHADER_L1=1,SHADER_L2=0,UNK10=1,UNK11=1,DESCRIPTOR_UNK12=0,DESCRIPTOR_UNK13=0 */
     0x08010e03, /* LOAD_STATE (1) Base: 0x0380C Size: 1 Fixp: 0 */
     0x00000c23, /*   GL.FLUSH_CACHE := DEPTH=1,COLOR=1,TEXTURE=0,PE2D=0,TEXTUREVS=0,SHADER_L1=1,SHADER_L2=0,UNK10=1,UNK11=1,DESCRIPTOR_UNK12=0,DESCRIPTOR_UNK13=0 */
     0x00000000, /* UNKNOWN (0) */
     0x00000000, /*  */
 }
 map->layer_type = 0x0;  /* (0) */
 map->no_z_offset = 0x0;  /* (0) */
 map->kernel_xy_size = 0x2;  /* (2) */
 map->kernel_z_size = 0x4;  /* (4) */
 map->kernels_per_core = 0x1;  /* (1) */
 map->pooling = 0x0;  /* (0) */
 map->pooling_xy_size = 0x1;  /* (1) */
 map->prelu = 0x0;  /* (0) */
 map->nn_layer_flush = 0x1;  /* (1) */
 map->kernel_data_type = 0x0;  /* (0) */
 map->in_image_data_type = 0x0;  /* (0) */
 map->out_image_data_type = 0x0;  /* (0) */
 map->in_image_x_size = 0x4;  /* (4) */
 map->in_image_y_size = 0x4;  /* (4) */
 map->in_image_x_offset = 0x0;  /* (0) */
 map->in_image_y_offset = 0x0;  /* (0) */
 map->unused0 = 0x0;  /* (0) */
 map->brick_mode = 0x0;  /* (0) */
 map->brick_distance = 0x0;  /* (0) */
 map->relu = 0x0;  /* (0) */
 map->unused1 = 0x0;  /* (0) */
 map->post_multiplier = 0x0;  /* (0) */
 map->post_shift = 0x17;  /* (23) */
 map->unused2 = 0x0;  /* (0) */
 map->no_flush = 0x0;  /* (0) */
 map->unused3 = 0x0;  /* (0) */
 map->out_image_x_size = 0x3;  /* (3) */
 map->out_image_y_size = 0x3;  /* (3) */
 map->out_image_z_size = 0x1;  /* (1) */
 map->rounding_mode = 0x1;  /* (1) */
 map->in_image_x_offset_bit_3 = 0x0;  /* (0) */
 map->in_image_y_offset_bit_3 = 0x0;  /* (0) */
 map->out_image_tile_x_size = 0x3;  /* (3) */
 map->out_image_tile_y_size = 0x3;  /* (3) */
-map->kernel_address = 0x3fffd00;  /* (67108096) */
+map->kernel_address = 0xcd237f;  /* (13443967) */
 map->kernel_z_size2 = 0x0;  /* (0) */
-map->in_image_address = 0xffff6000;  /* (4294926336) */
-map->out_image_address = 0xffff7000;  /* (4294930432) */
+map->in_image_address = 0x3348e240;  /* (860414528) */
+map->out_image_address = 0x89ffc500;  /* (2315240704) */
 map->image_caching_mode = 0x0;  /* (0) */
 map->kernel_caching_mode = 0x1;  /* (1) */
 map->partial_cache_data_unit = 0x0;  /* (0) */
 map->kernel_pattern_msb = 0x0;  /* (0) */
 map->kernel_y_size = 0x2;  /* (2) */
 map->out_image_y_stride = 0x3;  /* (3) */
 map->kernel_pattern_low = 0x0;  /* (0) */
 map->kernel_pattern_high = 0x0;  /* (0) */
 map->kernel_cache_start_address = 0x800;  /* (2048) */
 map->kernel_cache_end_address = 0xa00;  /* (2560) */
 map->image_start_address = 0x0;  /* (0) */
 map->image_end_address = 0x800;  /* (2048) */
 map->in_image_border_mode = 0x0;  /* (0) */
 map->in_image_border_const = 0x7d;  /* (125) */
 map->unused4 = 0x0;  /* (0) */
 map->kernel_data_type_bit_2 = 0x0;  /* (0) */
 map->in_image_data_type_bit_2 = 0x0;  /* (0) */
 map->out_image_data_type_bit_2 = 0x0;  /* (0) */
 map->post_multiplier_1_to_6 = 0x1f;  /* (31) */
 map->post_shift_bit_5_6 = 0x0;  /* (0) */
 map->unused5 = 0x0;  /* (0) */
 map->in_image_x_stride = 0x4;  /* (4) */
 map->in_image_y_stride = 0x4;  /* (4) */
 map->out_image_x_stride = 0x3;  /* (3) */
 map->unused6 = 0x0;  /* (0) */
 map->post_multiplier_7_to_14 = 0x61;  /* (97) */
 map->out_image_circular_buf_size = 0x0;  /* (0) */
 map->unused7 = 0x0;  /* (0) */
 map->per_channel_post_mul = 0x0;  /* (0) */
 map->out_image_circular_buf_end_addr_plus_1 = 0x3ffffff;  /* (67108863) */
 map->unused8 = 0x0;  /* (0) */
 map->in_image_circular_buf_size = 0x0;  /* (0) */
 map->unused9 = 0x0;  /* (0) */
 map->in_image_circular_buf_end_addr_plus_1 = 0x3ffffff;  /* (67108863) */
 map->unused10 = 0x0;  /* (0) */
 map->coef_zero_point = 0x80;  /* (128) */
 map->out_zero_point = 0x77;  /* (119) */
 map->kernel_direct_stream_from_VIP_sram = 0x0;  /* (0) */
 map->depthwise = 0x0;  /* (0) */
 map->unused11 = 0x0;  /* (0) */
 map->unused12 = 0x0;  /* (0) */
 map->unused13 = 0x0;  /* (0) */
 map->unused14 = 0x0;  /* (0) */
 map->unused15 = 0x0;  /* (0) */
 map->unused16 = 0x0;  /* (0) */
 map->further1 = 0x0;  /* (0) */
 map->further2 = 0x0;  /* (0) */
 map->further3 = 0x3ffffff;  /* (67108863) */
 map->further4 = 0x7f800000;  /* (2139095040) */
 map->further5 = 0xff800000;  /* (4286578688) */
 map->further6 = 0x0;  /* (0) */
 map->further7 = 0x0;  /* (0) */
 map->further8 = 0x0;  /* (0) */
   0x40, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x01, 0x00, 0x2c, 0x99, 0x0e, 0x00, 0x00,
   0x40, 0xea, 0x2c, 0xeb, 0x80, 0xaf, 0x80, 0x9b, 0x99, 0x80, 0x80, 0x13,
   0x80, 0x80, 0x80, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00, 0x00,
   0x00, 0x00, 0x00, 0x00
   0x69, 0xd3, 0x2d, 0x92, 0x07, 0x00, 0x64, 0x00, 0x0c, 0x22, 0x90, 0xd6,
   0x53, 0xc9, 0xe2, 0x48, 0xe6, 0x4c, 0xa8, 0xeb, 0xd2, 0xf3, 0xb0, 0xf4,
   0x2d, 0xa4, 0x3e, 0xf4, 0x0f, 0x7b, 0x98, 0x01, 0x41, 0x84, 0x92, 0x7e,
   0xfa, 0x19, 0xf5, 0xda, 0xb3, 0x5a, 0xb7, 0xf3, 0x97, 0x95, 0x12, 0xe7,
   0x51, 0x94, 0xcb, 0x5a, 0x1f, 0xa9, 0xc6, 0xc4, 0x1c, 0xa9, 0x92, 0x1f,
   0xf7, 0x64, 0xc3, 0xca
   0x77, 0x77, 0x77, 0x77, 0x77, 0x77, 0x77, 0x77, 0x77

This corresponds to a convolution with the following parameters:

  • 8x8x1 input tensor
  • 3x3x1 weight tensor
  • stride == 2

The differences are due to different addresses being allocated between runs, and some differences due to how Mesa's code is structured but that shouldn't affect the end result. 

At the top we have the payload of the submit IOCTL, followed by a struct with the configuration for the NN units themselves and then the buffers for the weights, input and output.

When running a convolution configuration that isn't yet supported, we will spot more differences and hopefully will be able to figure out the logic behind them.

Strided convolutions

The hardware doesn't really support strided convolutions, so these are "lowered" to 1-stride convolutions with added channels, as per this research paper:

By implementing the algorithm in the paper, we match the behavior of the blob, as with requantization. It refers only to 2D input tensors, so I will need to check how the blob behaves with 3D inputs and figure out the logic behind it.

For now I have chosen to do the tensor manipulation on the CPU, but later on we will be able to use the TP units in the HW for this, reducing latency.

Test suite

With so many different convolution parameters supported, I felt the need for a comfortable way of keeping regressions in check.

I wrote a simple pytest module that will generate a TFLite model with a single convolution operation, and the parameters and payloads will be changed according to the different parameters that we support.

At some point I will add a CI job, probably before sending the initial merge request.